Is this post for you?
You have invested in multiple systems - some collection of ERP, PLM, DAM, MAM, CMS, PIM, regulatory databases, supplier portals, and others. Some of those systems have been in place for years, and they hold real value: product knowledge, content assets, compliance records, domain expertise that took decades to accumulate.
And yet you still cannot get a straight answer about your products in one hit. Your AI initiatives keep hitting the same wall - the information underneath them is not reliable enough to trust the outputs. Your subject matter experts spend too much of their time reconciling data across systems instead of doing the work only they can do. Every new regulatory requirement lands like a crisis. Launching something that draws on everything you know requires a manual assembly project, not a configuration exercise.
If that is your situation, this post is for you. What you are describing is a context and meaning problem, and an information backbone is what resolves it.
Bottom line up front:
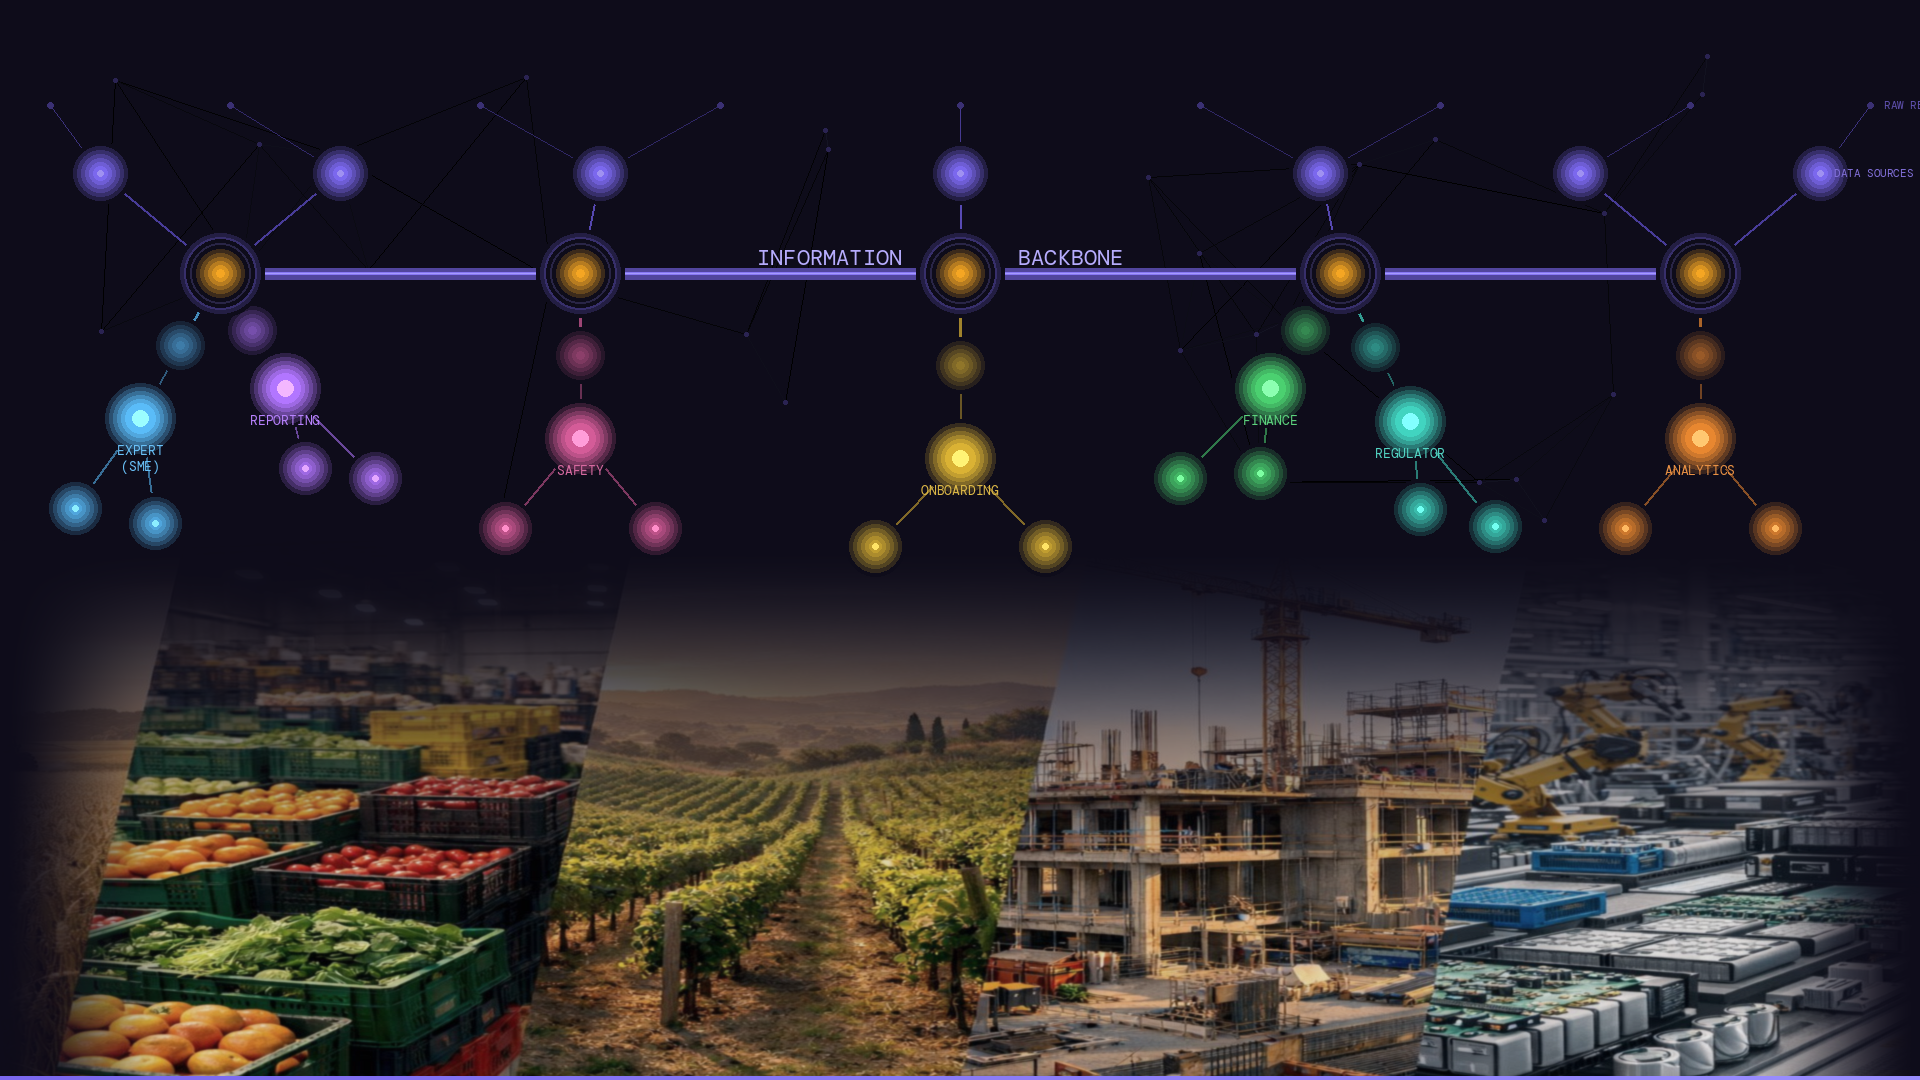
An information backbone is the place - in your organization's systems - where a human or a machine can go to answer a specific and important question, without having to guess, pattern-match, or cross-reference with a separate system. It gives certainty, context, and meaning. It is the structural foundation upon which everything else - your AI, your APIs, your regulatory outputs, your partner integrations - should be built.
What a backbone is not: four things organizations reach for first
- A data lake stores information at scale but does not govern meaning. You can have a very full data lake and still have no authoritative answer to the question "what does this product contain, and what regulations apply to it?"
- An API gateway manages how systems connect and communicate, not what the information being exchanged actually means. Two systems can be perfectly connected and still disagree about the definition of "material."
- A reporting layer produces outputs. The backbone is what makes those outputs trustworthy. Building better reports on top of ungoverned information does not fix the underlying problem.
- A document generation service bolted to the end of your process is perhaps the most common mistake, and worth naming directly. Organizations under pressure to produce compliant outputs - whether for partners, regulators, or new digital requirements - often reach for a service that generates those outputs from whatever information they already have. The output looks right. But the underlying meaning has not been governed. The next time a question is asked - by a different system, a different partner, a different regulatory authority - the process begins again from scratch, with the same fragmented foundation. The backbone is not at the end of the process. It is at the beginning.
A plain-language definition
Here is how I describe it when I want to be precise, steering clear of technologies and technical terms:
An information backbone is a shared, governed model of what your organization knows - structured so that the relationships between things are explicit, the definitions are controlled, and the reference data is maintained. It is the place where context and meaning live.
Think of it less like a filing system and more like a navigational chart. A filing system stores things. A chart tells you exactly where everything is, how it relates to everything else, and what it means to move from one place to another. When you need to answer a question - about a product, a component, a regulatory requirement, a supplier relationship - the chart gives you a certain answer, not a probable one. You do not have to triangulate across three systems to find it. You do not have to ask a subject matter expert to interpret it. The meaning is already there, built into the structure.
That certainty is the operational value of a backbone. Not just consistency - certainty.
The problems that a backbone resolves
Beyond the definition, here are the common symptoms that an information backbone resolves.
"We have the data, but we cannot trust it." The backbone resolves this not by adding more data, but by governing the meaning of the data you already have. When meaning is defined explicitly - in the model, not assembled at runtime - the outputs become defensible, and you can trace every answer to its governed source.
"Every AI project hits the same wall." The wall is not the AI. It is the absence of a foundation beneath it. AI tools consume meaning; when that meaning is inconsistent, ungoverned, or assembled at query time from fragmented sources, the outputs will be unreliable. A governed backbone gives AI something certain to work from - and makes AI tools interchangeable, because the meaning lives in the backbone, not in the tool.
"Our subject matter experts spend half their time on reconciliation." When meaning is fragmented across systems, the people who understand the domain become the translation layer between them. That is an expensive, invisible, and entirely avoidable tax on your most knowledgeable people. The backbone removes it by holding meaning once, governed by the experts who understand it, and making it available to every system that needs it.
"We cannot launch a product that uses all of our information - it is too fragmented." This is the commercial consequence of fragmented meaning. The assets and knowledge exist, but because different parts of the estate hold different versions of what things mean, assembling them into a coherent product requires manual effort that makes speed impossible. The backbone is what makes your information estate a coherent, launchable asset rather than a collection of siloed repositories.
"Our end-to-end information supply chain is not joined up." As well as information being siloed horizontally across multiple single-purpose systems, there is a common supply chain problem when data is not joined throughout the chain - from early R&D or commissioning through to end-use scenarios. This happens either because brittle legacy connections lose data when their caretakers move on, when reference data falls out of sync, or when model updates are not cascaded reliably; or because manual processes require humans to move context across boundaries as they step through the chain, leaving no machine-readable meaning behind them. The symptoms are the same either way: you cannot get a reliable answer to a question that spans the chain. Instead you have to go hunting and assembling.
"Every new regulatory requirement feels like a crisis." When machine-readable compliance outputs have to be assembled from systems that were never designed to produce them, every new mandate is a program of work. The backbone changes this. If your information is already held in a governed, machine-readable form, regulatory changes can be as simple as a reference data update, and even when they require a model change, a governed backbone is the most reliable and efficient means of making it - because machines understand it, and machines can execute it.
"We are locked into our current vendors because everything is entangled." When AI tools or platform vendors are deeply entangled with how your information is stored and interpreted, switching them means unpicking that entanglement. A current example is MCP tools and agent skills being configured with domain knowledge to handle the idiosyncrasies of a specific LLM; without an information backbone, this breaks when you change LLMs. A backbone separates meaning from tooling. The governed model lives independently of any vendor, so switching providers can happen against the APIs, without requiring a new articulation of domain context and meaning.
One important caveat: a backbone does not resolve every information problem. It does not automatically clean dirty data, replace legacy systems, or eliminate the need for change management. What it does is provide the governed foundation so that you can size up those problems and work through them systematically.
Simple Steps for COOs
- Run the certainty test on one important question. Pick a question your organization asks regularly - what does this product contain, which regulations apply, where was this batch sourced? Ask how many systems, people, and manual steps are currently needed to answer it with confidence. If the answer is more than one, you are assembling meaning at runtime. That is where your backbone work starts.
- Identify what is currently acting as your backbone. In most organizations, the backbone is a person - a subject matter expert whose institutional knowledge bridges the gap between disconnected systems. Name them. Then ask what happens to that knowledge when they are not available. The answer tells you what your ungoverned information risk actually is.
- Distinguish backbone decisions from system decisions. The information backbone is not a technology choice. It is an architectural and organizational decision about where meaning lives and who governs it. Make that decision first. The systems that host it and publish from it follow.
This post is part of The COO's Machine-Readable Information Backbone series.
Next in this series:
Post 5: The quiet power of reference data - governed, shared reference data is the stable vocabulary your backbone speaks in. Without it, every system downstream is guessing.
Post 6: AI observability in high-trust environments - if your AI outputs cannot be checked against a governed reference, you do not have observability. You have review. And in high-trust environments, review does not scale.
Post 7: What should a real information backbone look like? Seven characteristics of an AI context platform - the properties that separate a governed semantic foundation from a well-organized database, and why each one is checkable before you buy or build.
Previously in The COO's Machine-Readable Information Backbone series:
Post 3: Why AI needs a governed information backbone - not just better prompts - in regulated and high-trust environments, AI reliability is not a model problem. It is a foundation problem.
Post 2: Machine-readable information architecture is better for your people too - better information foundations improve the experience of the humans who work with product data every day.
Post 1: What does "machine-readable" really mean for digital product labels? - machine readability is a meaning problem, not a format problem.
Also in this series: Build or buy your information backbone? - why the true cost of building a governed information backbone is almost always underestimated.