Is this post for you?
Do your subject matter experts spend significant time manually mapping the same concept between systems - because different systems use different codes, classifications, or terms for the same thing? Do your AI outputs look plausible but feel untrustworthy, even when the underlying data appears to be in order? Does every regulatory submission require a reconciliation project before it can begin?
If that is your situation, this post is for you. Those symptoms almost always point to the same root cause: ungoverned reference data.
In Post 4, I defined what an information backbone is - the shared, governed, model-centric, machine-readable place where meaning lives, and the foundation from which everything else in your information estate should be built. In this post, I want to go one level deeper into something that tends to get treated as a technical detail, handed off to a data team, and quietly forgotten until something breaks.
That something is reference data. If the data model is the structure of your information backbone, reference data is the language it speaks in. Get it wrong - or fail to govern it - and the structure holds, but the meaning falls apart.
Bottom line up front:
Reference data is the shared, governed vocabulary that gives your information its meaning. Without it, your information backbone has structure but no stable language - and every system downstream is guessing.
The problem most people do not see coming
By the time a COO is thinking seriously about an information backbone, they have usually understood the core argument: machine readability is a meaning problem, not a format problem. They have thought about the model - the entities, the relationships, the governed structure. They are ready to invest in getting that right.
And then someone mentions reference data, and it sounds like a technical detail. A configuration task. Something for the data team to sort out once the architecture is agreed. The instinct is to delegate it and move on to more visible challenges.
Reference data is not a configuration task. It is the vocabulary the backbone speaks in - and without it, the model has structure but no stable language. The relationships are there. The meaning is not.
What reference data actually is
Your information backbone holds structure: a food product has ingredients, ingredients have allergen statuses, allergens have regulatory classifications. That structure tells you how things relate to each other. It does not, by itself, tell you what those things mean.
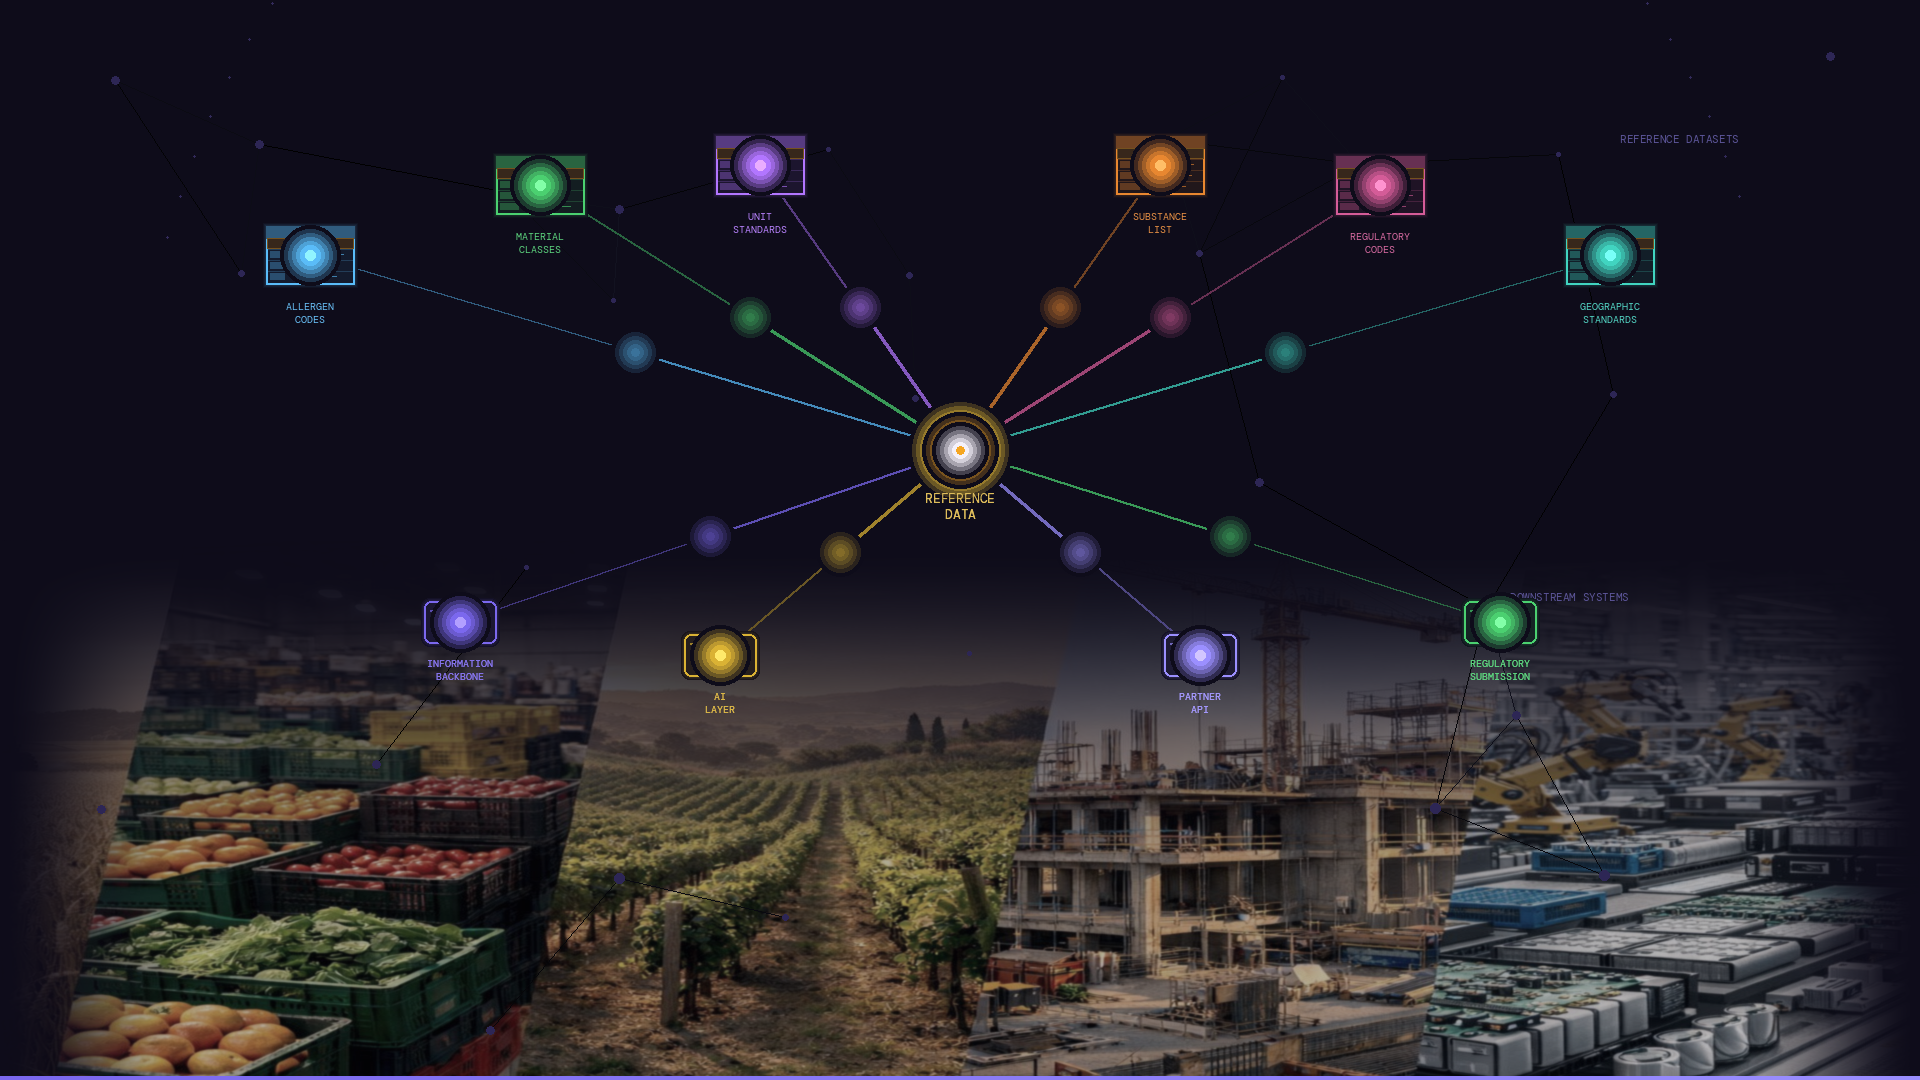
Reference data is what fills that gap. It is the agreed, governed list of authorized values - the controlled vocabulary - that the backbone draws from when it needs to express what a thing is, precisely.
When your system records that a product contains a specific substance, reference data is what defines that substance: its authorized name, its code, its classification, its regulatory status. When your system records a unit of measurement, reference data is what ensures that "gram" in your system means the same gram that your partner's system, your regulatory authority, and your consumer app all recognize.
Without reference data, a substance code is just a string of characters. With governed reference data, it maps to a defined entity with known properties and known relationships to everything else in the model.
Reference data is the shared dictionary of agreed-upon terms. It is what makes interoperability real rather than theoretical. You may also encounter it referred to as taxonomy, controlled vocabularies, code sets, or lookup data - different terms for the same foundational concept.
A concrete example: a food product label
A food manufacturer wants to produce a true digital product label - machine-readable, regulatory-compliant, and interoperable with supply chain systems, retail platforms, and consumer apps. The product contains wheat flour.
Simple enough. But consider what "wheat flour" means across the systems that need to consume it. The manufacturer's internal system records it under a product code used since the ERP was implemented in 2009. The supplier's system uses a different code from their own catalog. The retailer's platform expects it expressed against a standard ingredient taxonomy. The regulatory authority requires it mapped to an allergen classification scheme. A consumer app wants to display it in plain language with an allergen flag.
Without governed reference data, someone in the middle - almost always a subject matter expert, often the same one who has been doing it for years - manually reconciles those five representations every time the question is asked. They carry the mapping in their head. It works, mostly, until they are not there to add the meaning.
With shared, governed reference data, that reconciliation has already been done once. Every system draws from the same governed source, and nobody downstream has to guess.
That is the operational value of reference data. Not glamorous, but it marks the difference between a system that works and one that depends on a person who might not be there when the meaning needs to be rendered.
Why "governed" is the critical word
Reference data is only as good as its maintenance. An out-of-date reference dataset does not simply fail to help - it actively produces wrong answers with apparent confidence. A substance classified under a regulatory scheme that was revised eighteen months ago is not a neutral error. It is a compliance failure that looks like a correct output.
Governance for reference data means knowing, for every dataset your backbone uses: who owns it, how updates are managed, how changes propagate to the systems that depend on it, and what happens when a standard changes.
Some reference data comes from external sources - regulatory bodies, industry standards organizations, classification schemes maintained by third parties. Governance for those datasets means tracking when they are updated, deciding which changes are adopted, and having a reliable mechanism for propagating those changes through your systems. Some reference data is organization-specific - internal product codes, proprietary classifications, domain-specific terms and workflow controls that exist nowhere else. Governance for those datasets means clear ownership, a defined process for adding or retiring values, and version control that lets you trace when a value changed and why.
You may also decide to invest in enriching individual reference data concepts - adding synonyms, images, descriptions, localized translations - to make them findable, usable, and unambiguous across all the workflow, rendering, and integration scenarios your backbone needs to serve. How far to take that enrichment is an ROI decision, and it compounds the governance commitment: more properties per concept means more to maintain when something changes.
The backbone is not static. Reference data evolves as regulations change, standards are updated, and organizations restructure their product portfolios. The governance model needs to support that evolution without requiring a crisis program every time a code changes.
Where reference data comes from - and a word of warning
Most COOs will reasonably ask: do we have to build all of this from scratch? The answer is no. There is a rich ecosystem of existing reference datasets - industry classification schemes, regulatory substance lists, standard unit definitions, recognized allergen codes, geographic standards, currency lists. The skill is not in creating reference data from scratch but in selecting the right external sources, adopting them deliberately, and governing the subset that is specific to your organization.
This is where a very common mistake happens, and it happens for understandable reasons.
Wikidata is a good example. It is genuinely impressive: a massive, open, well-structured knowledge graph covering an enormous range of concepts, with rich properties for each one. It is free, well-maintained, and widely used. The instinct to reach for it is sensible. The problem is that organizations often load in far more than they need - thousands of concepts when they need dozens, and dozens of properties per concept when they need three or four. The overhead of governing all of that, keeping it current, and understanding what you have actually imported quickly becomes unmanageable.
The principle that applies here is the same one that applies to the backbone model itself: load just what you need to answer the questions you will actually ask of your data. If your food product label needs to reference allergen classifications, import the allergen classification scheme. If your regulatory submission needs substance codes, adopt the relevant regulatory list. You will need to govern whatever you import, so govern only what earns its place.
Without governed reference data, your experts become the reference data
It is worth naming the operational cost concretely, because it tends to be invisible until someone starts adding it up.
Without governed reference data, your subject matter experts become the reference data. They carry the authoritative definitions in their heads, in their inboxes, in the spreadsheets they have been maintaining for years. They are the ones who know that the internal code maps to the regulatory code, that the supplier's term means the same as the standard term, that the classification changed when the regulation was updated in 2022.
When they leave, that knowledge goes with them. When a standard changes, the update propagates inconsistently or not at all. When a new system needs to interoperate, someone has to manually map between vocabularies - and that someone is usually the same person who is already doing five other things.
This is not a hypothetical cost. It is the hidden tax that most organizations with complex product portfolios are already paying, invisibly, every day. It shows up as reconciliation time, as compliance risk, as the reason your AI outputs cannot be trusted, as the reason your SMEs are not doing the work only they can do. Reference data governance is what removes that tax - not completely, not overnight, but systematically and in a way that compounds as the governed vocabulary grows.
The unglamorous work that unlocks everything else
Reference data will not feature in a board update on digital transformation. It will not get its own workstream in the program plan. It will not be the thing that anyone gets excited about in a steering committee.
But it is the work that determines whether everything else holds together. The backbone is the structure. Reference data is the language. You need both. The organizations that treat reference data governance as a strategic asset - rather than a technical chore - are the ones whose backbones actually deliver on the promise of machine-readability.
Simple Steps for COOs
- Ask where your authoritative definitions actually live. For any critical classification in your product or regulatory information - substance codes, allergen statuses, material categories - ask: is this defined once, in a governed model that every system draws from? Or is it defined in a person's head, a spreadsheet, or a legacy system that nobody fully controls? The answer tells you where your reference data risk lies.
- Treat reference data adoption as a scoping decision, not a loading exercise. When evaluating external reference datasets or ontologies, resist the instinct to import everything available. Define the specific questions your backbone needs to answer, and import only the concepts and properties required to answer them. Govern that subset rigorously before expanding.
- Make reference data ownership explicit before you build. For every reference dataset your backbone will use - internal or external - name an owner, define an update process, and establish how changes propagate to every system that depends on it. A backbone with ungoverned reference data is a database with a well-structured front end, not a governed foundation.
This post is part of The COO's Machine-Readable Information Backbone series.
Next in this series:
Post 6: AI observability in high-trust environments - if your AI outputs cannot be checked against a governed reference, you do not have observability. You have review. And in high-trust environments, review does not scale.
Post 7: What should a real information backbone look like? Seven characteristics of an AI context platform - the properties that separate a governed semantic foundation from a well-organized database, and why each one is checkable before you buy or build.
Previously in The COO's Machine-Readable Information Backbone series:
Post 4: What is an information backbone? A plain-language definition for operational leaders - written for organizations that already have systems, already have data, and are still asking why none of it feels reliable.
Post 3: Why AI needs a governed information backbone - not just better prompts - in regulated and high-trust environments, AI reliability is not a model problem. It is a foundation problem.
Post 2: Machine-readable information architecture is better for your people too - better information foundations improve the experience of the humans who work with product data every day.
Post 1: What does "machine-readable" really mean for digital product labels? - machine readability is a meaning problem, not a format problem.
Also in this series: Build or buy your information backbone? - why the true cost of building a governed information backbone is almost always underestimated.