At some point in almost every serious information backbone conversation, the question comes up: could we build this ourselves?
It is a reasonable question. Your organization has engineering capability, existing systems to integrate with, and a deeper understanding of your own domain than any vendor does. There is also an understandable instinct - particularly in regulated sectors where information is a competitive and compliance asset - to keep strategic infrastructure in-house.
This post works through that question honestly. The answer is not always "buy." But the conditions under which "build" is the right answer are narrower than most organizations initially believe - because the true cost of building a governed information backbone for a high-trust environment is almost always underestimated.
Bottom line up front:
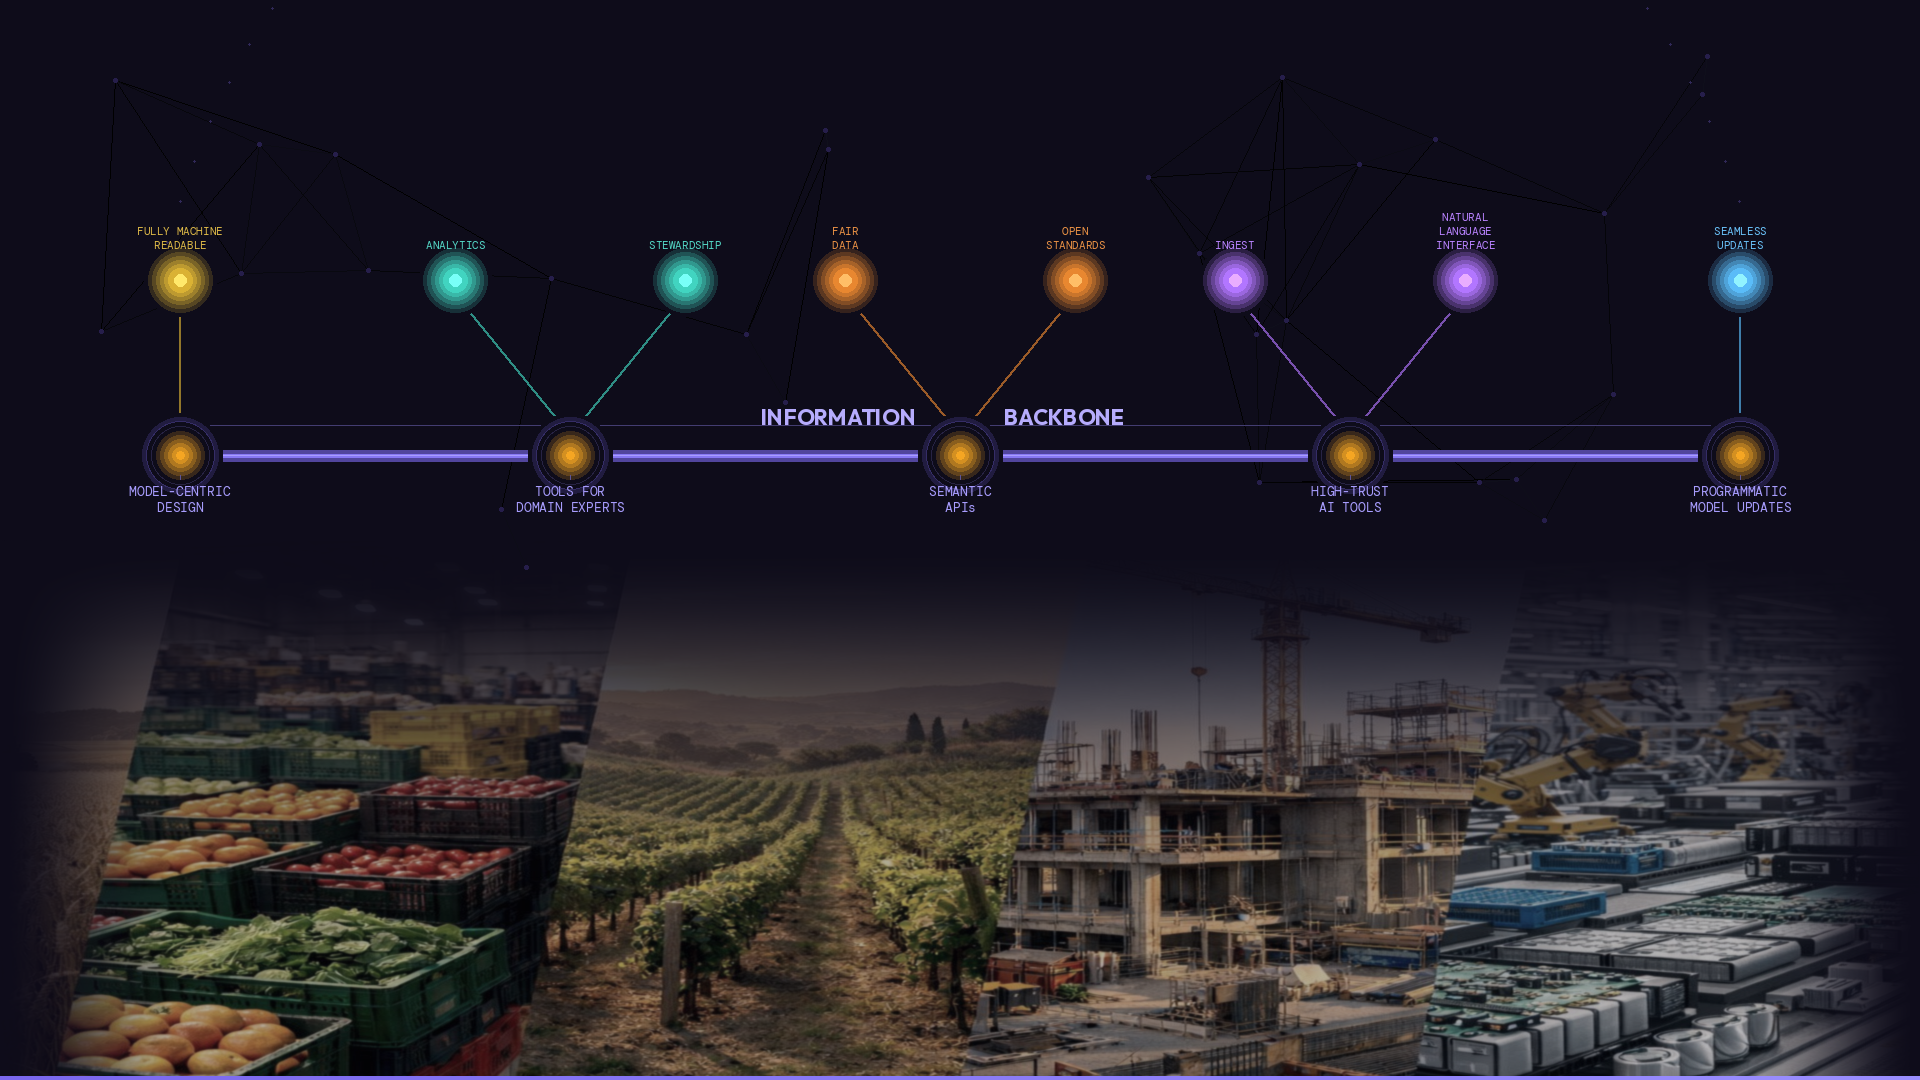
Building a governed information backbone is not a data engineering project. It is a sustained investment in model-centric infrastructure, SME-native tooling, semantic APIs, and operational model governance - including the ability to update your information model programmatically as your domain, regulations, and organization evolve. The organizations that underestimate this do not just overspend. They end up with something that cannot do the job.
What you are actually building: the scope most estimates miss
The first mistake in most build estimates is a failure to define the scope accurately. When organizations say "we could build this," they typically have in mind a graph database, a data model, some APIs, and a front end for SMEs to interact with. That is the visible part. The harder parts are what break the estimate.
- Model-centric design, not just data storage. The backbone does not just store information - it governs meaning. That means entities, explicit relationships, controlled vocabularies, and reference data that map to how your domain actually works. Designing this well requires deep domain engagement and an information architecture discipline that is distinct from data engineering.
- SME-native tooling. The backbone only works if the people who understand the domain can maintain it without IT involvement. Building tooling that exposes the information model to subject matter experts - in a form they can actually use, that reinforces governance rather than undermining it - is a UX and information design challenge that most engineering teams underestimate significantly. It typically gets built, rebuilt, and rebuilt again.
- Semantic APIs, not just data APIs. An API that exposes data fields is straightforward to build. An API that reflects the governed information model - expressing relationships, classifications, and shared meaning in a form that partner systems and regulatory platforms can consume directly - is a different proposition. It requires a governed semantic model and a means to expose that model through the APIs.
- Infrastructure for a regulated environment. Graph database hosting, scaling, security, access controls, versioning, backup, failover, and auditability are not optional in regulated and high-trust environments. They are the baseline.
- High-trust AI. AI operating on ungoverned data has to make its best guess and fill gaps at query time. In regulated environments, that is not good enough. A properly structured information backbone eliminates gap-filling through a tightly defined model, well-governed reference data, and machine-readable, tightly validated instance data.
- Operational model governance. Your information model will change - regularly - due to new regulatory requirements, product portfolio evolution, domain expansion, and reference data updates. The tooling and processes to manage those changes in a controlled, non-interruptive way, without breaking downstream systems, are themselves significant engineering and governance challenges.
The cost that surprises most organizations: model updates
Of all the dimensions above, the one that most consistently surprises organizations in the build analysis is the last one: ongoing model governance, and in particular the cost and operational risk of updating the information model as things change.
In a regulated environment, your model is not static. Regulations change, product categories evolve, new substances get classified, and reference data constantly updates. An organization operating across multiple jurisdictions or product lines will face model change as a recurring operational reality, not an occasional exception.
When you build your own backbone, every model change is a program of work - engineering effort to update the schema, impact analysis to understand what downstream systems are affected, testing to verify that the change has propagated correctly, and coordination with the teams whose systems depend on the model. This is not a problem that goes away as the backbone matures. It is a structural property of in-house builds that do not have model change designed in from the outset.
A purpose-built backbone platform supports programmatic model updates via API - meaning that model changes can be structured, versioned, and executed through a controlled programmatic interface, rather than requiring bespoke engineering effort each time. Reference data changes, relationship updates, new classification schemes - these are operations a mature backbone platform is designed to handle.
The hidden cost of the SME tooling problem
There is a second cost dimension that deserves specific attention, because it tends to be systematically underestimated in build proposals: the cost of building tooling that domain experts can actually use.
Subject matter experts need a way to work with the information model - to populate it, validate it, maintain reference data, and manage classifications - without requiring IT involvement for routine operations. The specification is clear. The build is not.
Building tooling that genuinely puts SMEs in control of the governed model requires the tooling to be designed around the information model itself, not around what a development team found natural to build, and not around a generic data management UI that has been adapted. When the UX is built before the model is sound, the tooling embeds assumptions about meaning that the model then has to contort itself to accommodate. The result is a system that sits one step away from the backbone it was supposed to expose.
Most organizations that have attempted to build SME tooling for an information backbone have built it more than once. The first version does not survive contact with real domain experts working at scale. The second is better. The third is usually when the scope of the challenge becomes clear. That iteration cost is rarely in the original build estimate.
A TCO comparison across the key dimensions
The table below maps the primary cost dimensions against the build and buy options. Costs and approaches vary significantly by organization, scale, and domain - the intent is to make the comparison across dimensions explicit, not to present a specific financial model.
The pattern across these dimensions is consistent. In a build scenario, each line item requires dedicated engineering, architecture, or operational investment. In a platform deployment, each is a capability that is configured, not built - with the exception of the domain-specific model work, which requires genuine subject matter expertise regardless of the path taken.
The right question to ask before you decide
The most useful framing for the build vs buy decision is not "can we build this?" - the answer to that question is almost always yes, in principle. The more useful question is: what would we need to maintain in perpetuity to keep this trustworthy, and is that the best use of our engineering capacity?
A governed information backbone in a high-trust environment is not a system you build and hand over, it is an operational capability that requires ongoing investment: in model governance, in reference data management, in tooling that keeps SMEs productive, and in the ability to update the model as the world changes. Every one of those demands is a permanent claim on engineering and governance resources. For most organizations, those resources are better directed at the domain knowledge and product differentiation that only they can build - not at recreating infrastructure that already exists as a mature, purpose-built platform.
Simple Steps for COOs
- Before any build estimate, ask for the ongoing cost (not just the build cost). Request a breakdown that includes model governance, SME tooling iteration, infrastructure operations, and the cost of model updates over a three-year horizon (not just the cost of the initial build).
- Test the model update assumption directly. Ask your engineering team: if a regulatory requirement changed the classification scheme for a key product category, how long would it take to update the model, migrate the data, test it, and propagate that change to every downstream system? The answer tells you how nimble your platform will be.
- Apply the SME tooling test before committing. Before signing off on a build approach, ask who will maintain the information model when the initial engineering team moves on. If the answer requires IT involvement for routine updates, the tooling has not been built for the people who need to use it.
This post is part of The COO's Machine-Readable Information Backbone series.
Also in this series:
Post 5: The quiet power of reference data - governed, shared reference data is the stable vocabulary your backbone speaks in. Without it, every system downstream is guessing.
Post 6: AI observability in high-trust environments - if your AI outputs cannot be checked against a governed reference, you do not have observability. You have review. And in high-trust environments, review does not scale.
Post 7: What should a real information backbone look like? Seven characteristics of an AI context platform - the properties that separate a governed semantic foundation from a well-organized database, and why each one is checkable before you buy or build.
Previously in The COO's Machine-Readable Information Backbone series:
Post 4: What is an information backbone? A plain-language definition for operational leaders - written for organizations that already have systems, already have data, and are still asking why none of it feels reliable.
Post 3: Why AI needs a governed information backbone - not just better prompts - in regulated and high-trust environments, AI reliability is not a model problem. It is a foundation problem.
Post 2: Machine-readable information architecture is better for your people too - better information foundations improve the experience of the humans who work with product data every day.
Post 1: What does "machine-readable" really mean for digital product labels? - machine readability is a meaning problem, not a format problem.